life update: after 2.5 incredible years at Bloomberg AI, i will be joining @AnthropicAI
Shijie Wu
MTS @AnthropicAI. Opinions are my own.
← Home · 31 posts from @EzraWu on X, 2019–2024, kept here after leaving the platform.
2024
2023
i still remember EMNLP (first conference) and multilingual BERT was released. soon after it i dropped my project and started tinkering multilingual BERT with pytorch-pretrained-bert. you simply can’t overstate the contribution of @huggingface Transformers to NLP
Thomas Wolf @Thom_Wolf · May 18, 2023This is crazy! I still remember when I started coding Transformers with Victor and Tim one cold night of October 2018 in Bruxelles after attending the EMNLP conference and its social event at the Royal Museums of Fine Arts
And today, 5 years after, Hugging Face Transformers is the 37th most popular repository ever on GitHub and the 2nd AI library to pass 100k stars ⭐️ on it …
thrilled to share BloombergGPT! we survived the tornado 🌪️ and we can’t wait for what comes next!
Mark Dredze @mdredze · Mar 31, 2023I’m delighted to have been part of this amazing team that spanned @Bloomberg’s #AI Engineering & #ML Product and Research group in CTO. This was a thrilling and exhausting experience, and we’re excited to share with the larger research community what we learned.
In science, each of us knows that what he has accomplished will be antiquated in ten, twenty, fifty years. That is the fate to which science is subjected; it asks to be surpassed & outdated. Whoever wishes to serve science has to resign himself to this fact
-science as a vocation
2022
Looking back, is the unsupervised representation alignment across language in multilingual LMs (ie mBERT, XLM-R, mT5 etc) an instance of emergent ability?
PaperEmergent Abilities of Large Language ModelsFinally got a chance to share the hooding (thanks @mdredze ❤️) and my thesis 🎉
Thesis: How Do Multilingual Encoders Learn Cross-lingual Representation? arxiv.org/abs/2207.05737
Final piece: Zero-shot Cross-lingual Transfer is Under-specified Optimization arxiv.org/abs/2207.05666
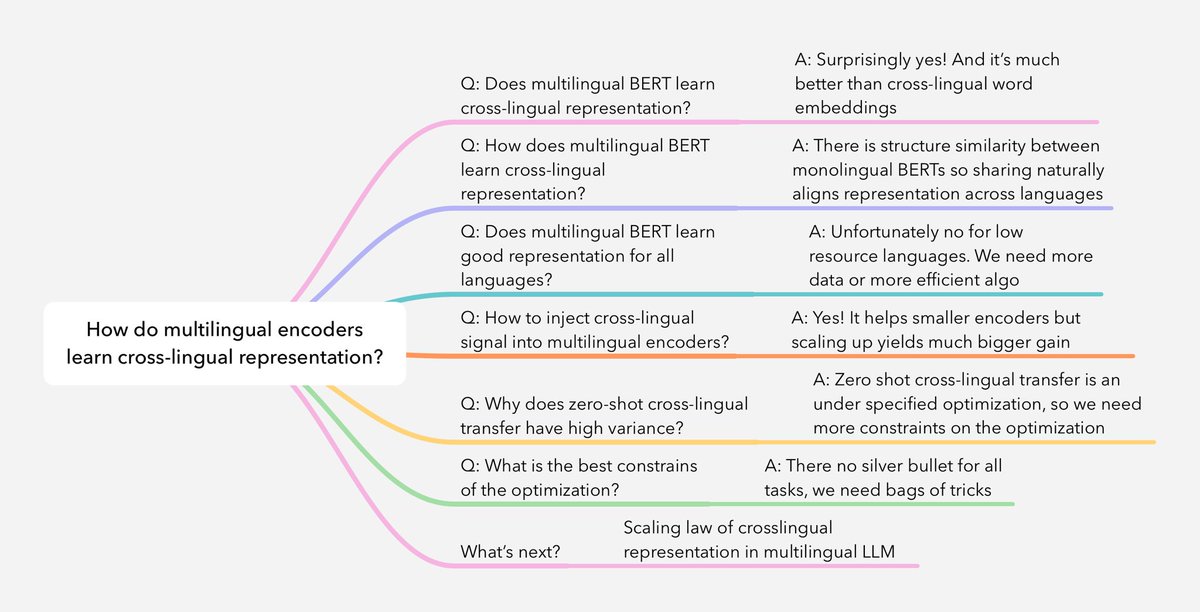
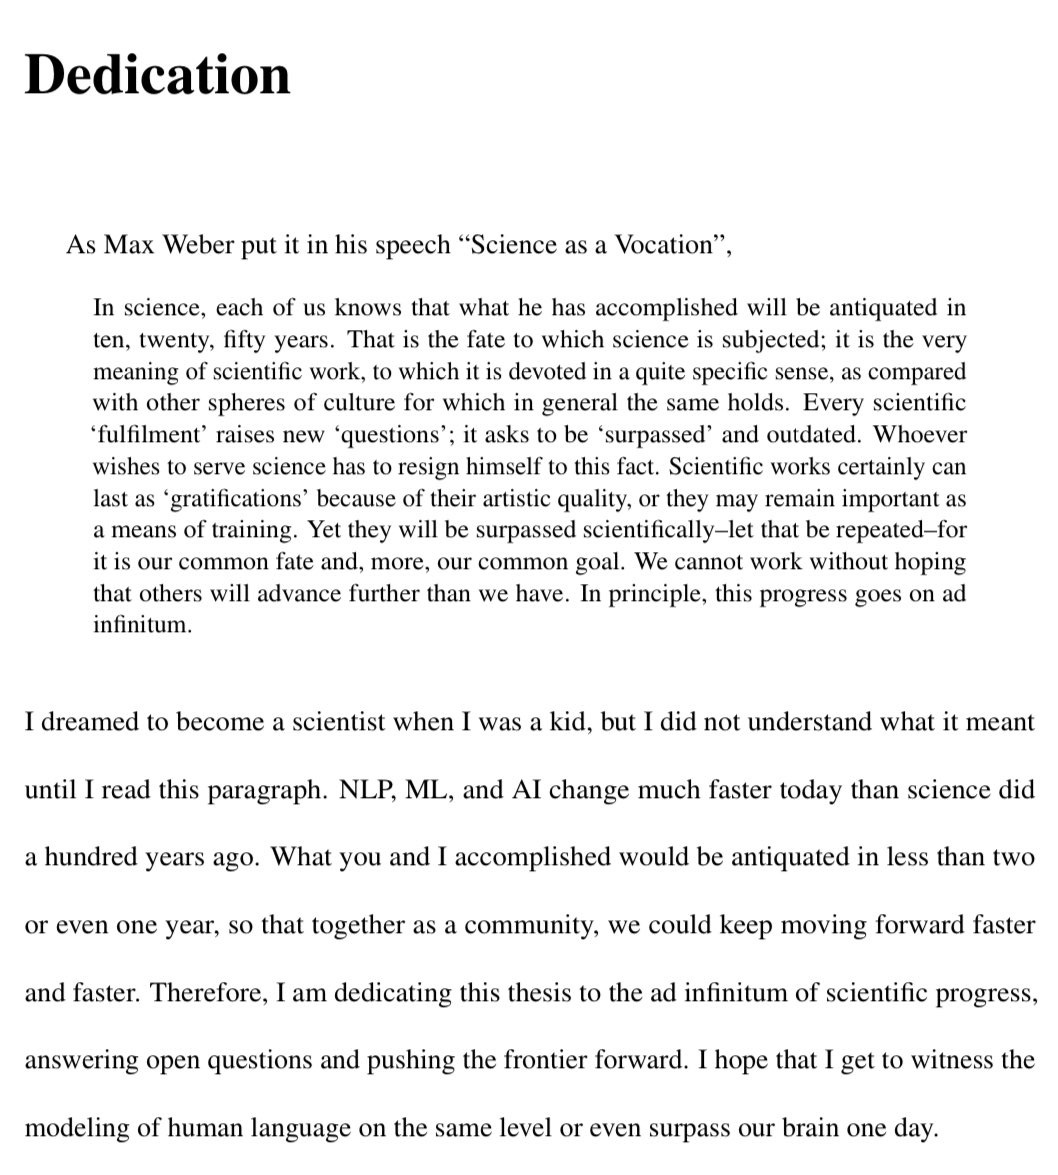
I finished writing my thesis 9 months ago and now we got BLOOM, the first open access multilingual LLM, thanks to @BigscienceW
I can’t wait to see what we as a community could do to answer the scaling questions of cross-lingual representation in multilingual LLM!
So excited for #NAACL2022, my first in person conference in three years (I was still a first year phd student back then 🙈)! Come say hi and I love to chat about crosslingual NLP, LLMs and what ur working on ❤️
2021
Life update: I have successfully defended my thesis and will join Bloomberg AI in January
Q: What's the best choice to improve zero-shot cross-lingual transfer performance if u can’t manually annotate any data?
A: The best setup is task dependent, so try multiple setups! 📈
Check out our #EMNLP2021 paper “Everything Is All It Takes” arxiv.org/abs/2109.06798 [1/4]
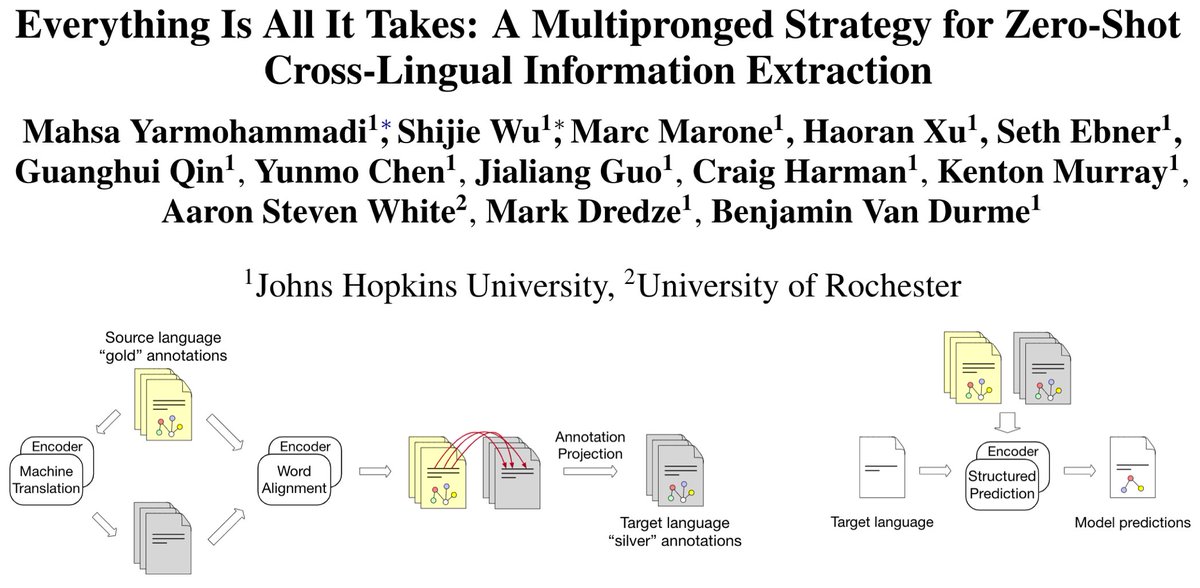
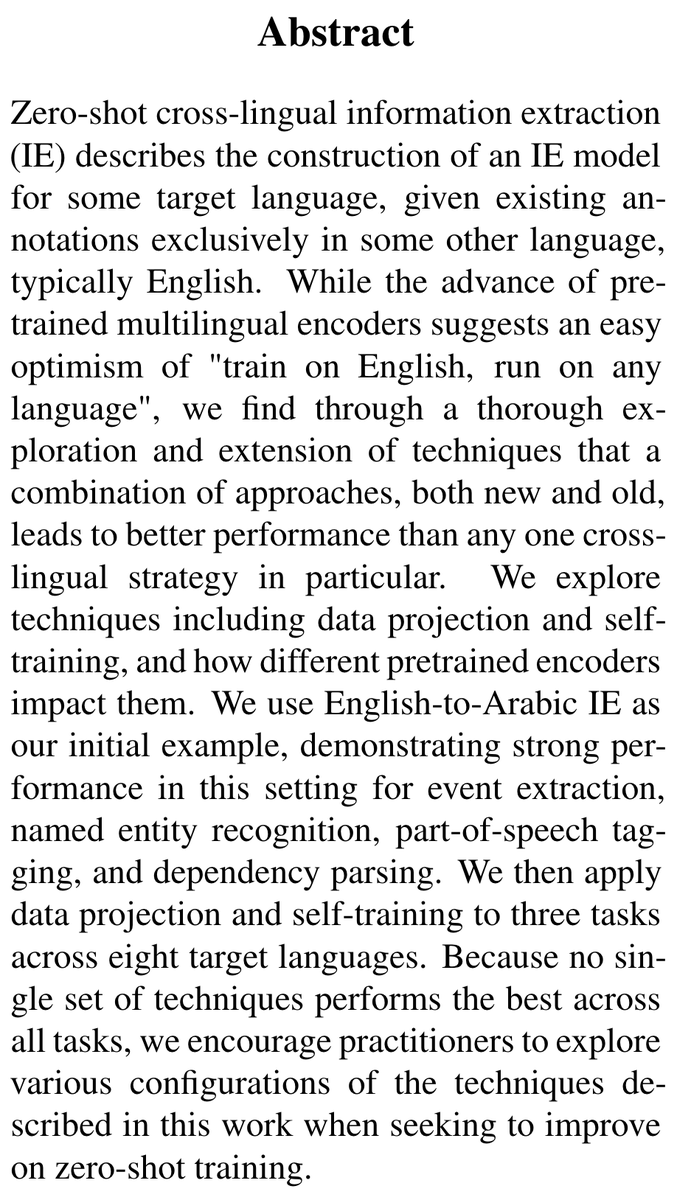
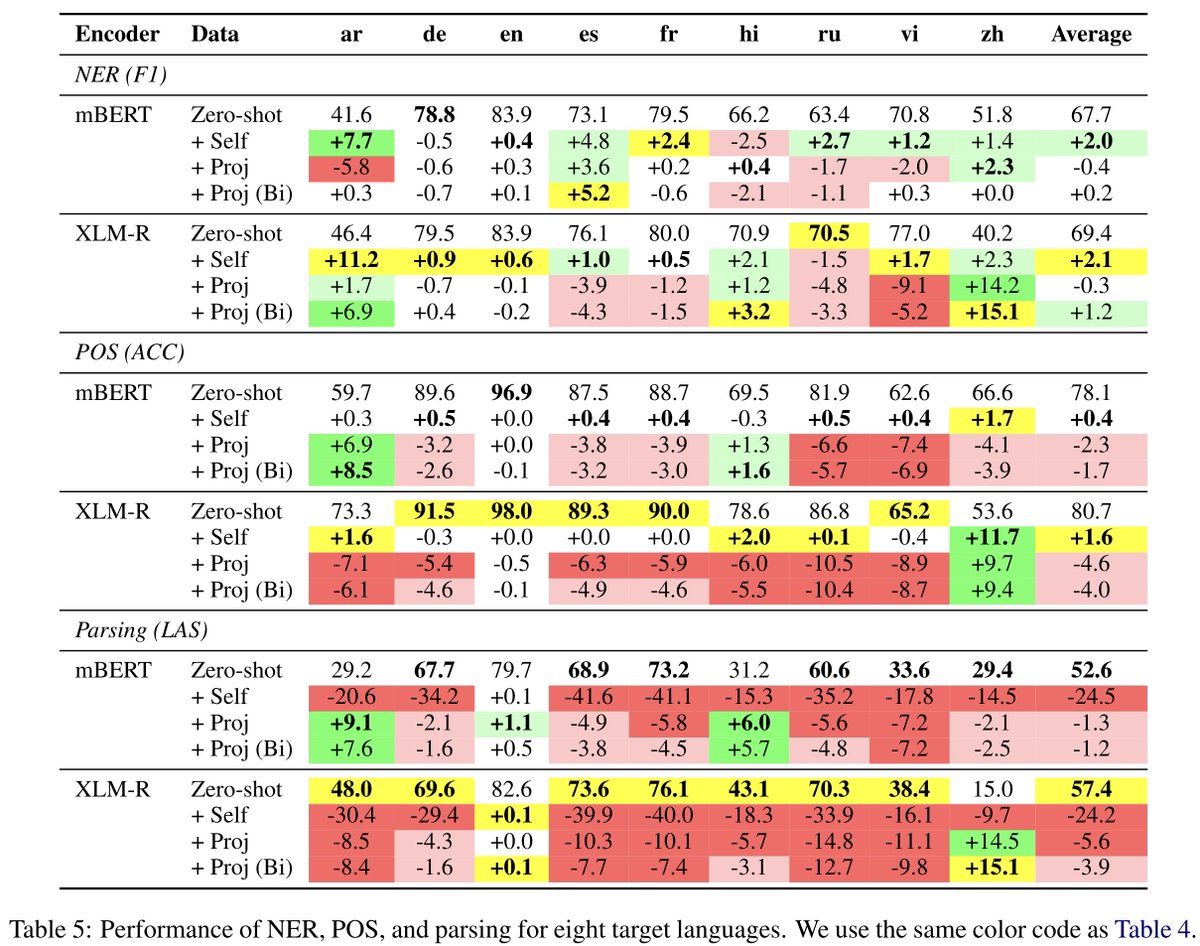
We conducted extensive experiments on EN-->AR as test case including: 1️⃣ data projection pipeline with various MT models and aligners; 2️⃣ impact of encoder on MT and aligner; 3️⃣ impact of fine-tuning on aligner; 4️⃣ self-training as controlled comparison of data projection. [2/4]
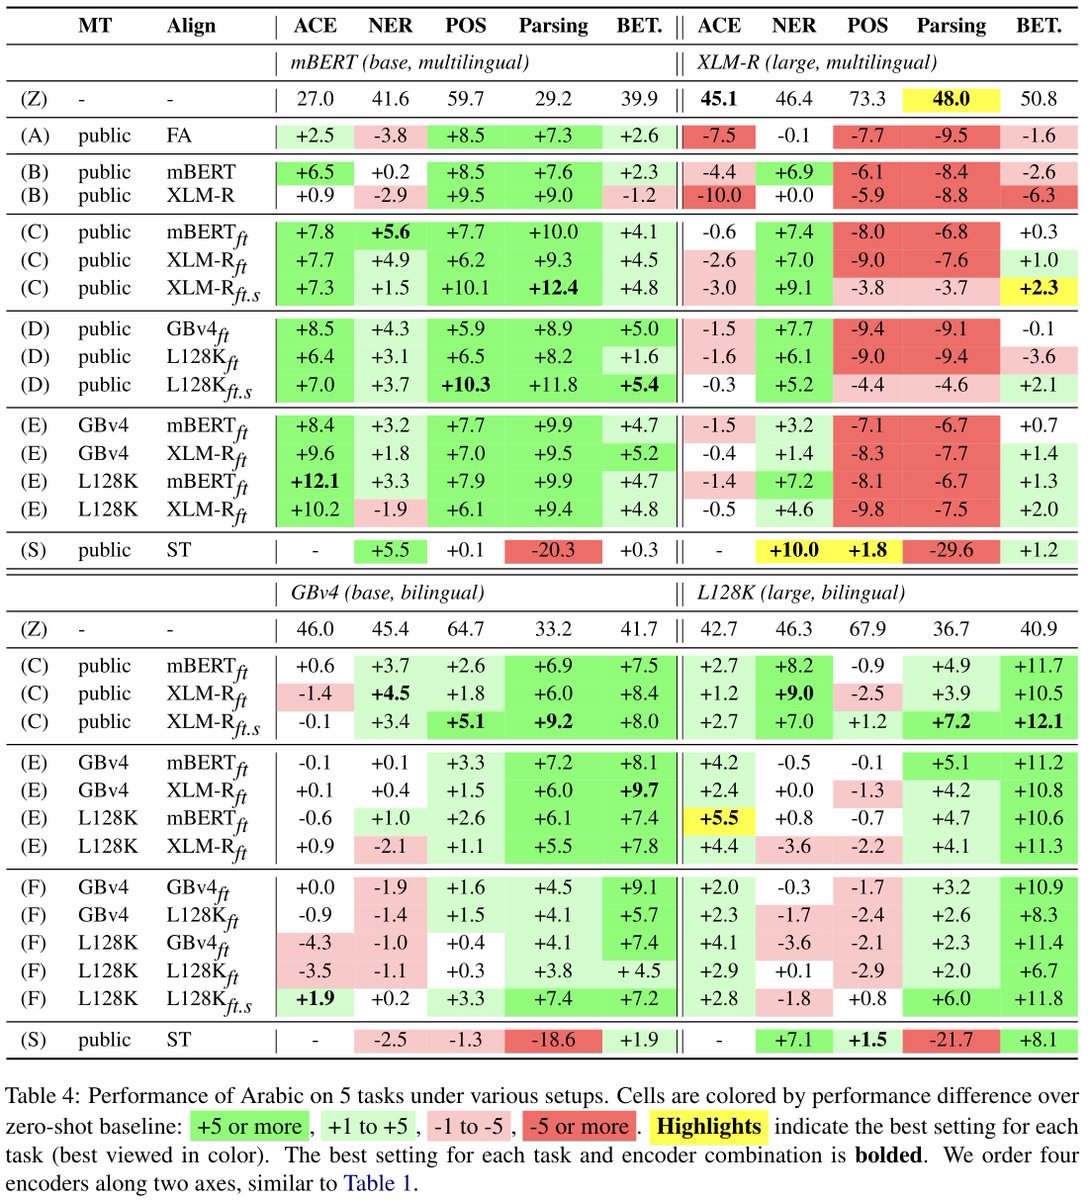
We also conducted multilingual experiments with 8 target languages.
This is a joint work with Mahsa Yarmohammadi @ruyimarone @fe1ixxu @_t_sne @hiaoxui @YunmoChen Jialiang Guo @charman @kentonmurray @aaronsteven @mdredze @ben_vandurme @jhuclsp [3/4]
Resources we released:
* Large English-Arabic encoder huggingface.co/jhu-clsp/rober…
* Data projection github.com/shijie-wu/cros…
* Arabic denormalization toolkit github.com/KentonMurray/A… [4/4]
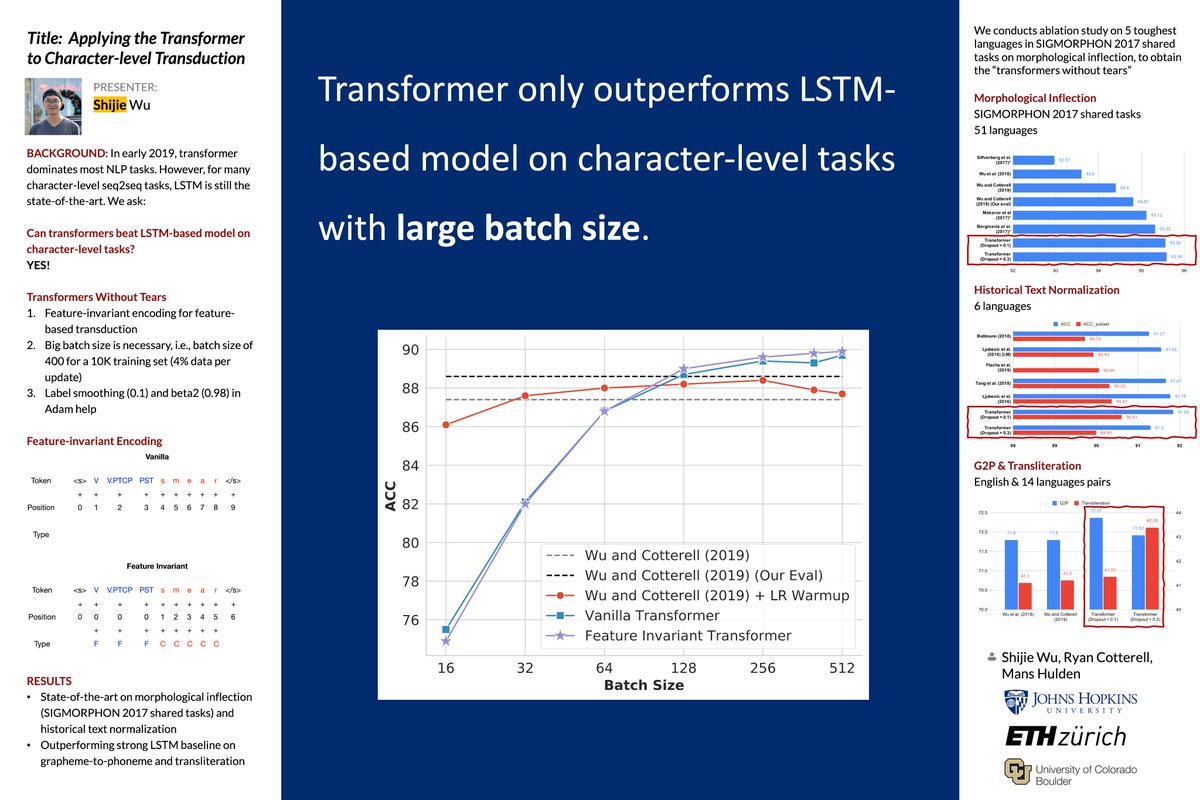
Happy to share that our paper on "Applying the Transformer to Character-level Transduction" won the #EACL2021 honorable mention for short paper awards! Congrats @ryandcotterell and Mans!
Talk slideslive.com/38954605/apply…
Paper arxiv.org/abs/2005.10213
Code github.com/shijie-wu/neur…
2020
Q: Do Explicit Alignments Robustly Improve Multilingual Encoders?
My talk: slideslive.com/38939127/
Code: github.com/shijie-wu/cros…
Q: Which *BERT should I use?
@nlpaxia's talk: slideslive.com/38939146/
#EMNLP2020
Summary of "Do Explicit Alignments Robustly Improve Multilingual Encoders?"
#EMNLP2020
Summary of "Which *BERT? A Survey Organizing Contextualized Encoders"
#EMNLP2020
Interesting work showing word translation from mBERT with template: "The word ‘SOURCE’ in LANGUAGE is: [MASK]."
PaperIt’s not Greek to mBERT: Inducing Word-Level Translations from Multilingual BERTHappy to share our #EMNLP2020 paper (w/ @mdredze) on contrastive cross-lingual alignment titled “Do Explicit Alignments Robustly Improve Multilingual Encoders?”
Expand thread for TL;DR ... (1/3)
Paper arxiv.org/abs/2010.02537
Code github.com/shijie-wu/cros…
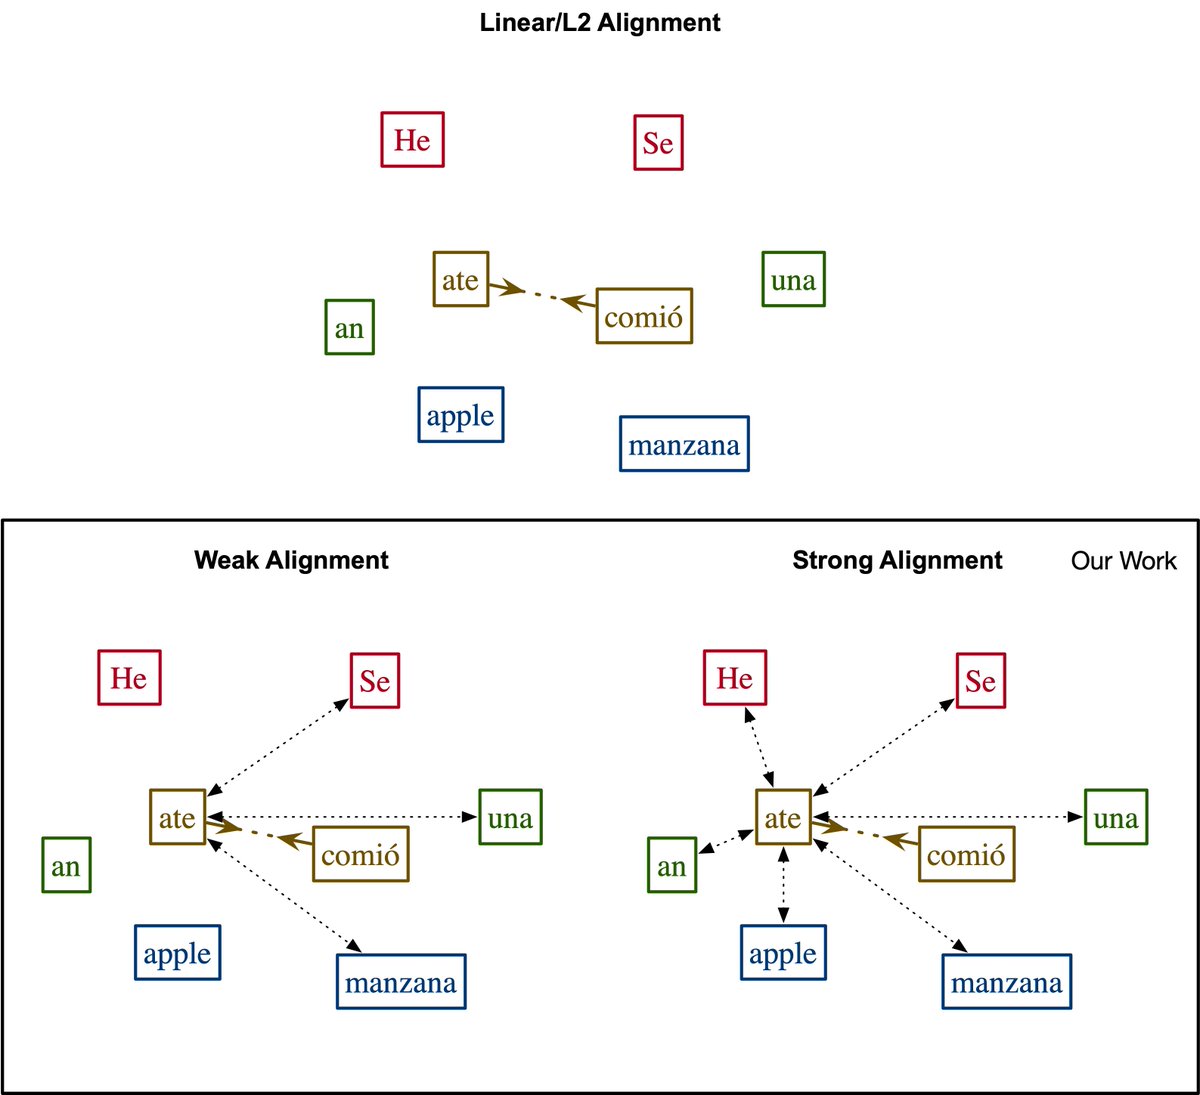
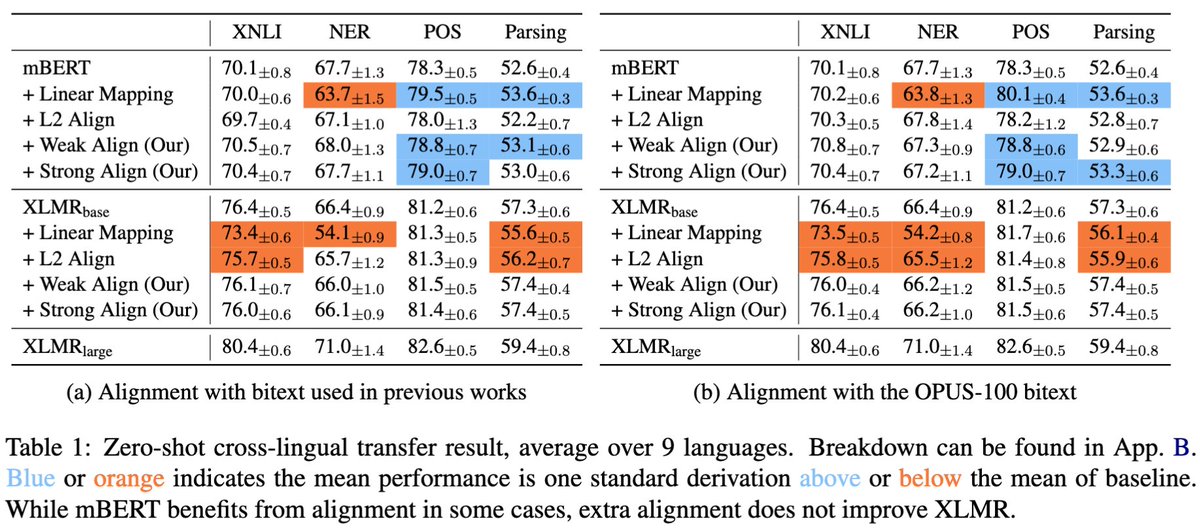
... (1) contrastive alignment consistently outperforms L2 alignment and performs more robustly than linear mapping (2) zero/few-shot cross-lingual transfer (includ. benchmarks) needs to report mean & variance w/ different seeds, similar to the few-shot learning community .. (2/3)
… (3) quality of bitext has small impact on downstream performance (4) while alignment helps mBERT in some cases, none of the methods we considered improve XLMR (5) a bigger model leads to much bigger gain compared to ad-hoc alignment, without any need for bitext (3/3)
With unlimited acknowledgements at #emnlp2020, we have enough space to give credits to all the open source software that make our research possible 😜 scipy.org/citing.html
EMNLP 2020 @emnlp2020 · Oct 5, 2020[UPDATE] The camera-ready instructions were modified. Acknowledgements NO LONGER COUNT towards the total page limit! So feel free to thank as many people as you like :)
Happy to share that one short paper "Do explicit alignments robustly improve massively multilingual encoders?" w/ @mdredze and one long paper "Which *BERT? A Survey Organizing Contextualized Encoders" w/ Patrick Xia and @ben_vandurme got accepted to #EMNLP2020 (1/2)
The first one is on contrastive cross-lingual alignment and how we evaluate zero-shot cross-lingual transfer.
The second one is a survey on contextualized encoders.
(2/2)
#acl2020nlp The theme track is one of the tracks I enjoy the most this year. If you haven't, go check out all the nice talks taking stock of our field. Highly recommended!!! Personal opinion: the theme track should be a regular track.
So honored to win best long paper at #Repl4NLP #acl2020nlp. Thanks @mdredze @jhuclsp! sites.google.com/view/repl4nlp2…
Earlier post · Jul 7, 2020Q: Are All Languages Created Equal in Multilingual BERT? A: Check out "Are All Languages Created Equal in Multilingual BERT?" Talks: Tweets: (3/3)Happy to share my two talks on multilingual representation learning in #acl2020nlp: Emerging Cross-lingual Structure in Pretrained Language Models (w/ @alex_conneau et al at @facebookai) and Are All Languages Created Equal in Multilingual BERT? (w/ @mdredze at @jhuclsp) (1/3)
Q: Why do models like multilingual BERT and XLM-R learn cross-lingual representation?
A: Check out "Emerging Cross-lingual Structure in Pretrained Language Models"
Talks: virtual.acl2020.org/paper_main.536…
Tweets: (2/3)
Q: Are All Languages Created Equal in Multilingual BERT?
A: Check out "Are All Languages Created Equal in Multilingual BERT?"
Talks: slideslive.com/38929782/are-a…
Tweets: (3/3)
Happy to share a new paper "Are All Languages Created Equal in Multilingual BERT?" arxiv.org/abs/2005.09093
The short answer is *NO* and we provide experiments to show why.
Work with @mdredze, accepted in #Repl4NLP workshop at #acl2020nlp
We show the bottom 30% of languages in mBERT learn poor representation. We show for low resource languages, mBERT > bilingual BERT (paired w/ ling. similar language) > monolingual BERT, suggesting the culprit is poor data-efficiency & lack of data (two sides of the same coin)
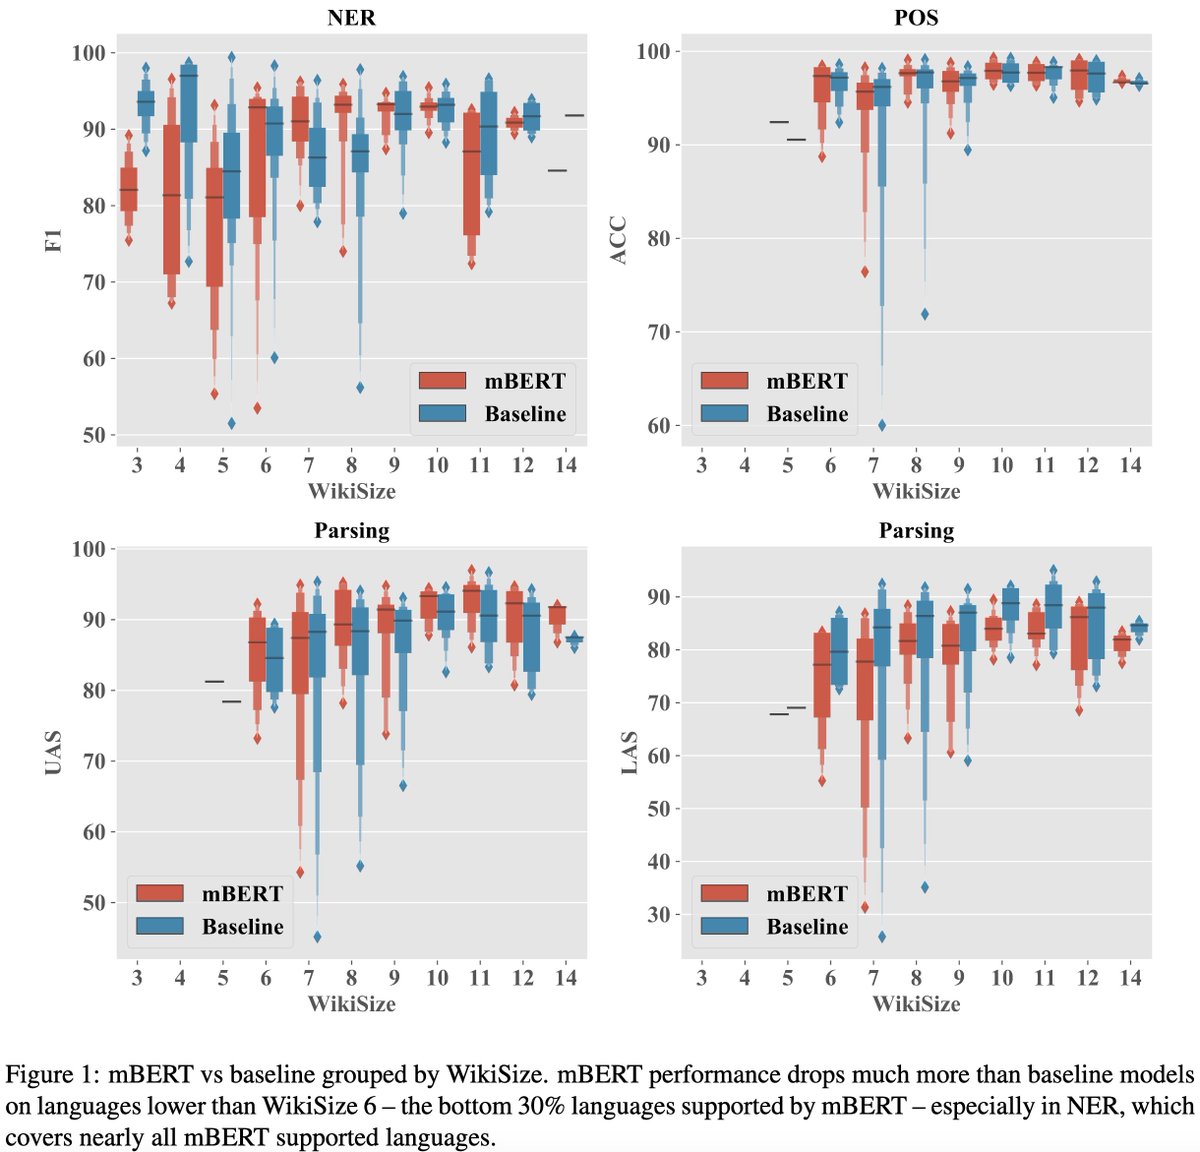
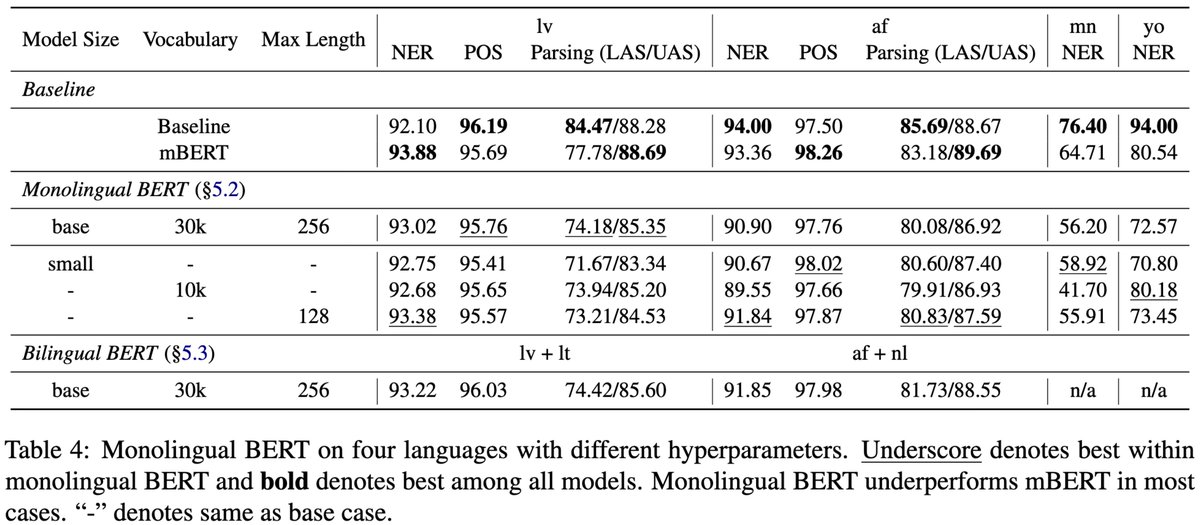
To learn better representation for low resource languages in the future, we need to collect more data (like XLM-R arxiv.org/abs/1911.02116) or a more data-efficient pretraining technique (like ELECTRA openreview.net/forum?id=r1xMH…)
The #acl2020nlp camera ready is now on arXiv. It additionally includes results on aligning both bilingual and monolingual BERT with linear mapping for cross-lingual transfer. Aligning bilingual BERT only helps parsing but not NER.
Earlier post · Nov 6, 2019Excited to share my summer intern project @facebookai “Emerging Cross-lingual Structure in Pretrained Language Models” We dissect mBERT & XLM and show monolingual BERTs are…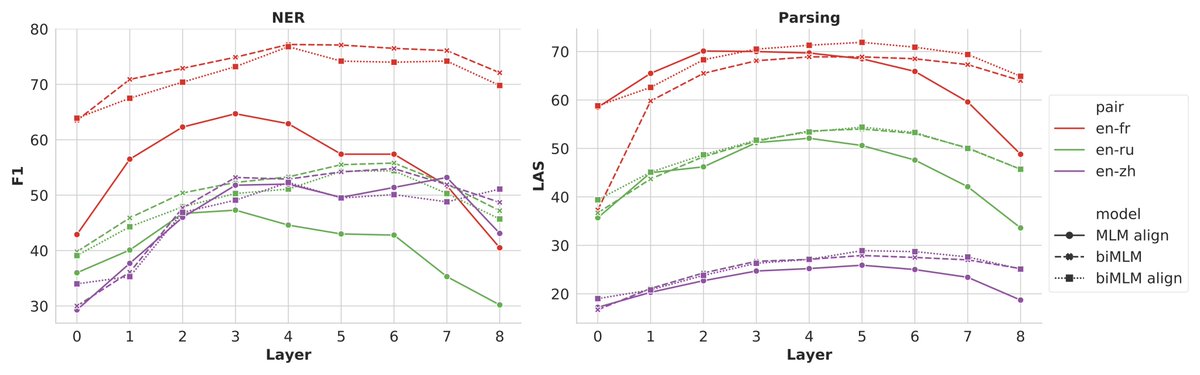
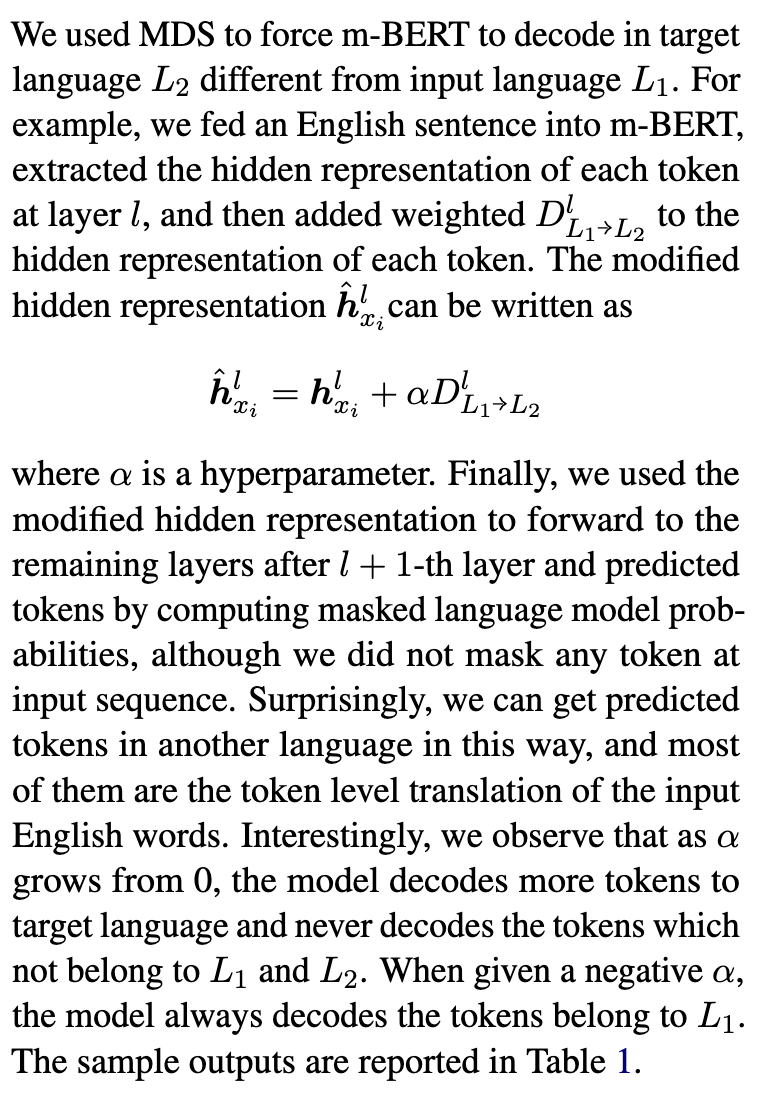
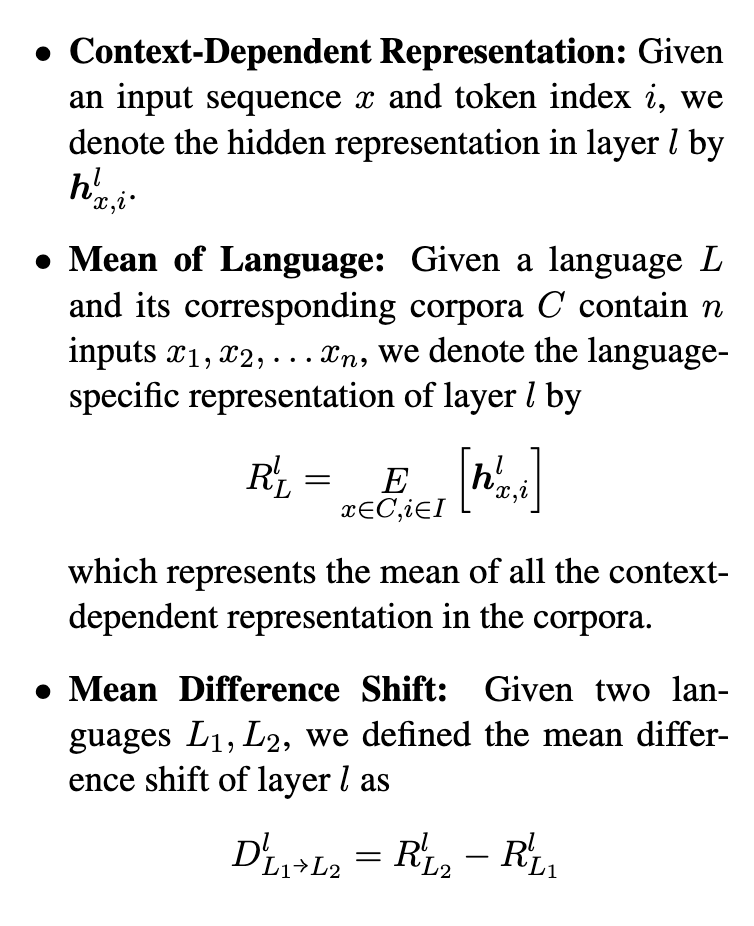
Interesting paper by authors from National Taiwan University shows that you can manipulate multilingual BERT to generate related foreign word by shifting the hidden layer with the difference of languages embeddings
PaperA Study of Cross-Lingual Ability and Language-specific Information in Multilingual BERT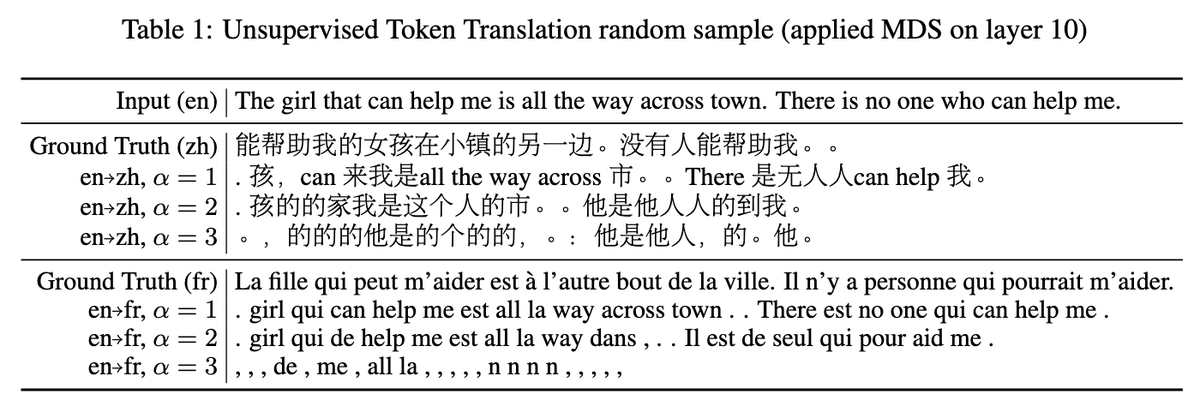
I am happy to share that I passed the GBO (thesis proposal) on multilingual encoder :)
I am excited to share that our paper is accepted to #acl2020
Earlier post · Nov 6, 2019Excited to share my summer intern project @facebookai “Emerging Cross-lingual Structure in Pretrained Language Models” We dissect mBERT & XLM and show monolingual BERTs are…2019
Excited to share my summer intern project @facebookai “Emerging Cross-lingual Structure in Pretrained Language Models” arxiv.org/abs/1911.01464
We dissect mBERT & XLM and show monolingual BERTs are similar
Joint work with @alex_conneau @AimeeLiS @LukeZettlemoyer @vesko_st
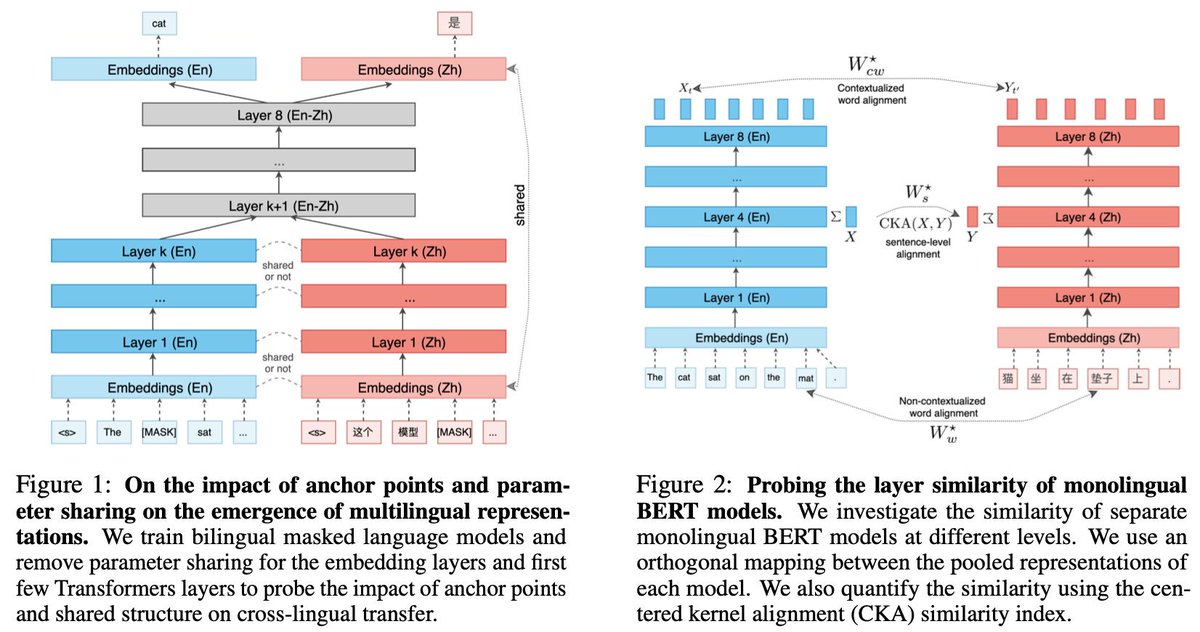
We offer an ablation study on bilingual MLM considering all relevant factors. Sharing only the top 2 layers of the transformer finally break cross-lingual transfer. Factors importance: parameter sharing >> domain similarity, anchor points, language universal softmax, joint BPE
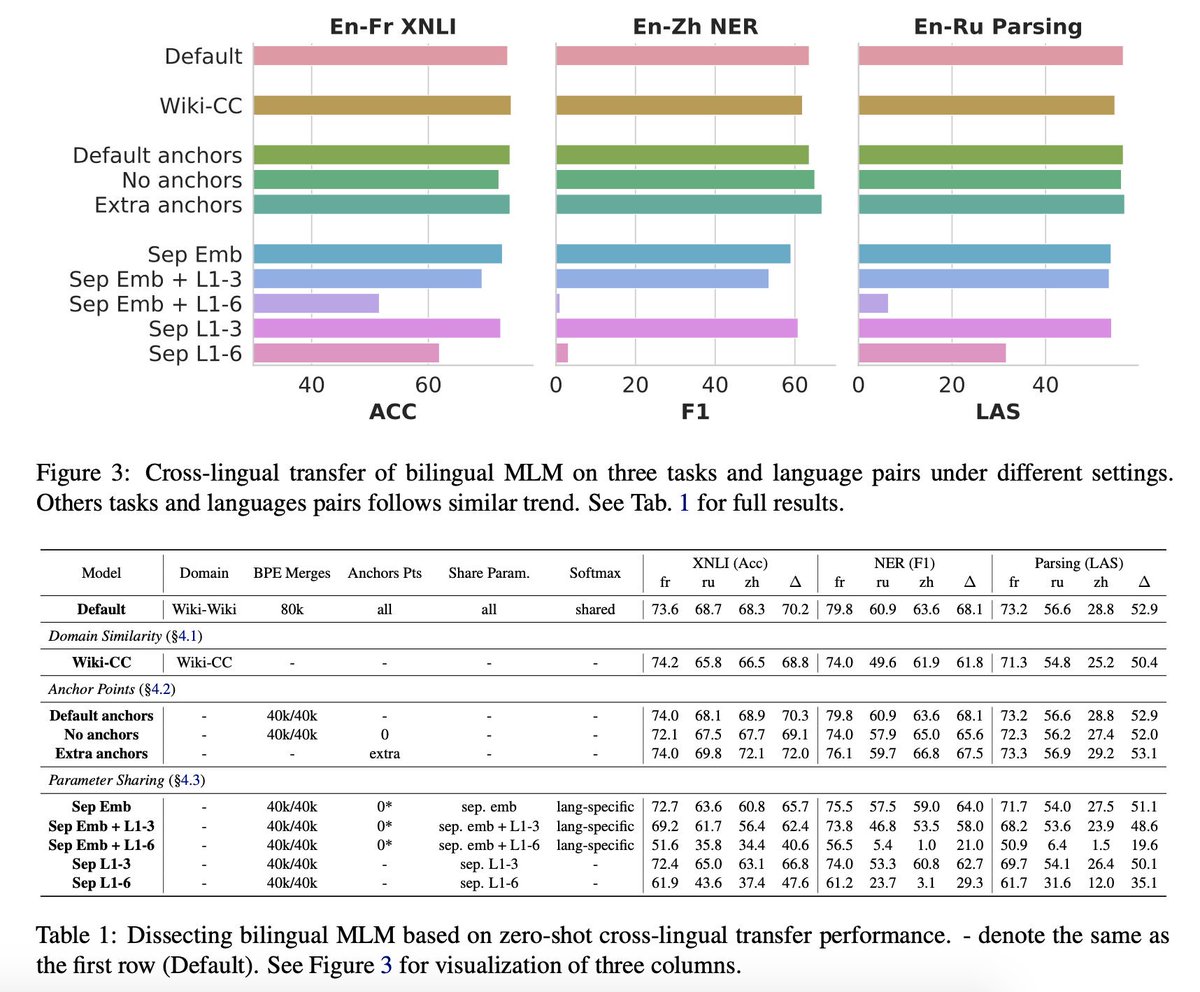
Q: Why sharing transformer parameters only learn cross-lingual space?
H: Independent trained monolingual BERTs are similar.
We can align monolingual BERT representation at word-level & sentence level with orthogonal mapping. CKA visualizes similarity of monoling. & biling. BERT
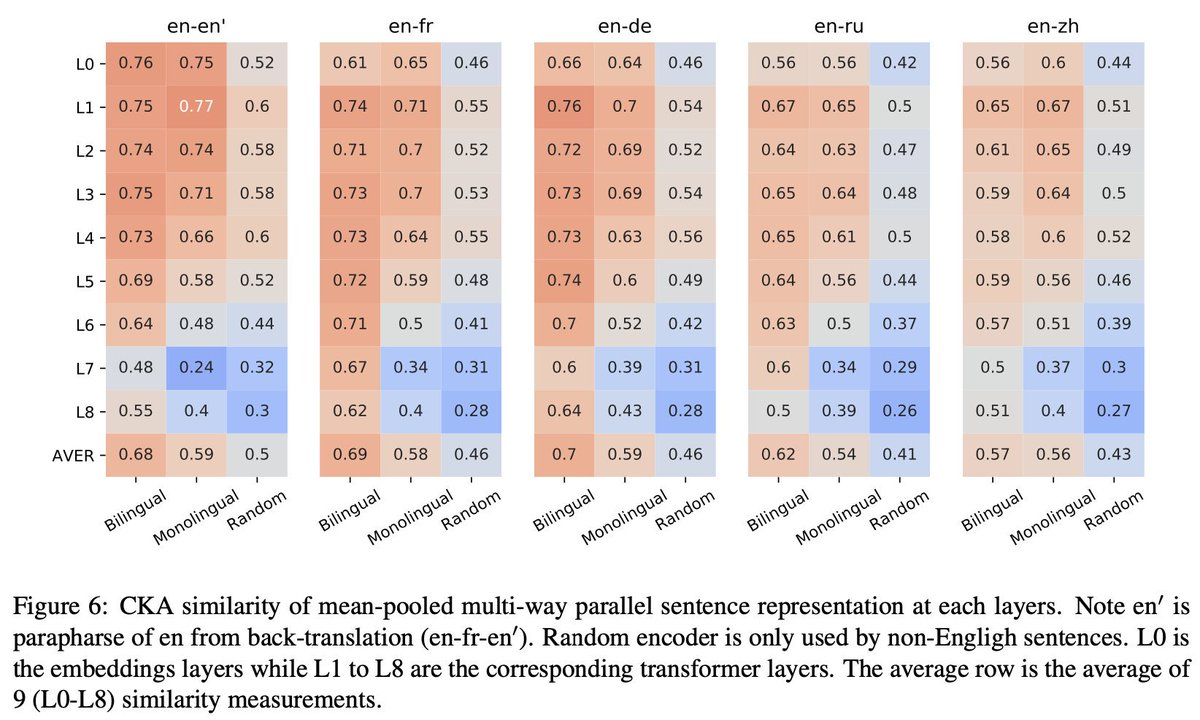
We are missing #emnlp2019 but check out the camera-ready version. aclweb.org/anthology/D19-…
Earlier post · Apr 22, 2019Check out our paper on the surprising effectiveness of mBERT We consider zero-shot cross-lingual transfer (NLI, Doc classification, NER, POS tag, dep. parsing). mBERT outperforms…If you are interested in our #emnlp2019 mBERT paper, don’t miss our latest preprint on understanding multilingual masked language models. It give insight to some of the questions from the mBERT paper.
Earlier post · Nov 6, 2019Excited to share my summer intern project @facebookai “Emerging Cross-lingual Structure in Pretrained Language Models” We dissect mBERT & XLM and show monolingual BERTs are…A really nice figure of representation similarity across languages from the encoder of @GoogleAI's massively multilingual NMT system
PaperInvestigating Multilingual NMT Representations at Scale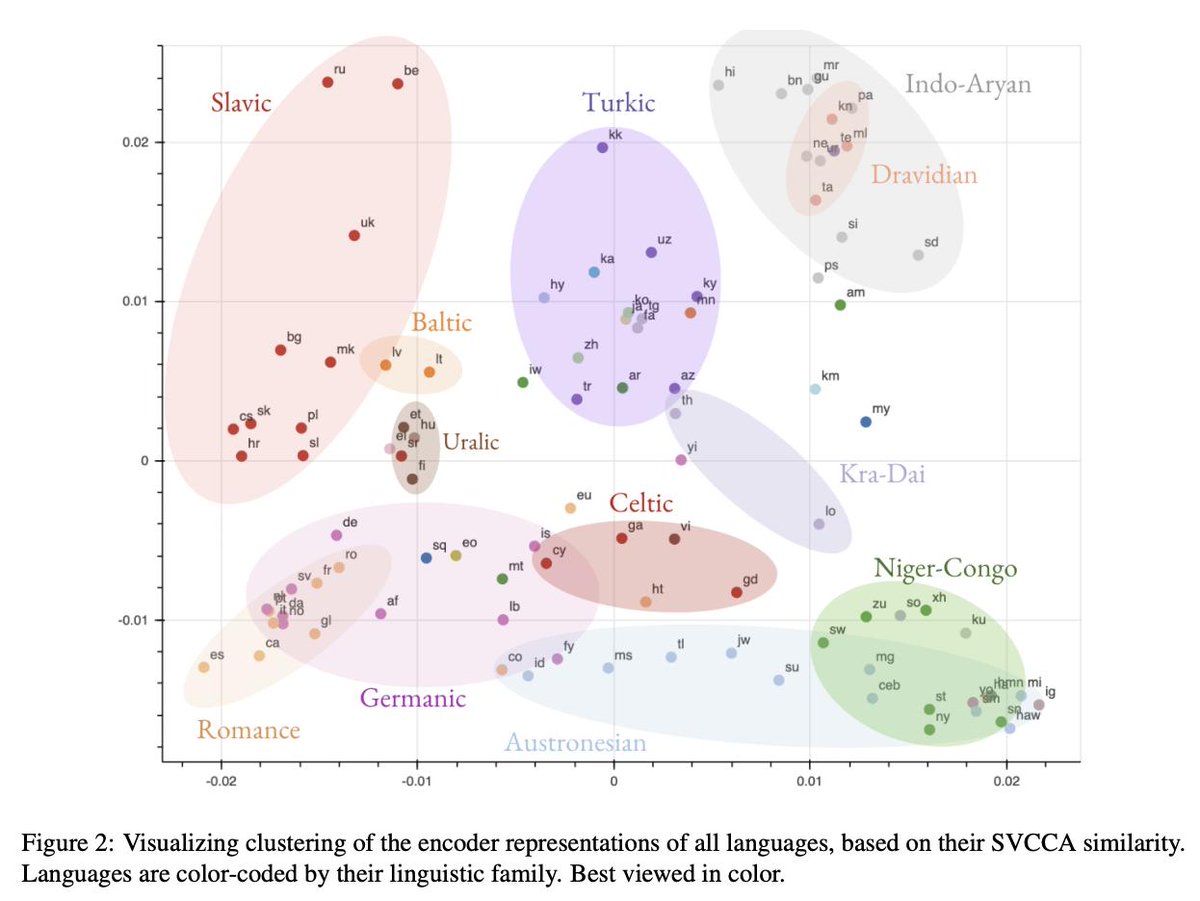
Pertraining BERT on more African languages would probably help MT & other NLP tasks. Currently mBERT/XLM100 only cover a small set of African languages, probably due to relative small Wiki size. Common Crawls helps but we need more effort on building open monolingual data.
Jade Abbott @alienelf · Sep 1, 2019Calling all African NLPers!
Goal: Let's publish a paper with NMT baselines for all African languages
Instructions https://github.com/jaderabbit/masakhane
Let's put African NMT on the map! 🌍🔥💗
Exicted to share that this paper will appear at @emnlp2019 .
Earlier post · Apr 22, 2019Check out our paper on the surprising effectiveness of mBERT We consider zero-shot cross-lingual transfer (NLI, Doc classification, NER, POS tag, dep. parsing). mBERT outperforms…Taking time off from internship at @facebookai and traveling to @ACL2019_Italy. Really excited to present two papers! (1/3)
Monday 1:50-3:30 pm at Arsenale: "Exact Hard Monotonic Attention for Character-Level Transduction". Paper arxiv.org/abs/1905.06319. Work with @ryandcotterell (2/3)
Wednesday 1:50-2:10 pm at Hall 6: "Morphological Irregularity Correlates with Frequency". Paper arxiv.org/abs/1906.11483. Work with @ryandcotterell and Timothy J. O'Donnell (3/3)
Our paper "Exact Hard Monotonic Attention for Character-Level Transduction" was accepted at @ACL2019_Italy. Paper is available at arxiv.org/abs/1905.06319 and code is available github.com/sigmorphon/cro… as the baseline of @sigmorphon 2019 shared task. Joint work with @ryandcotterell
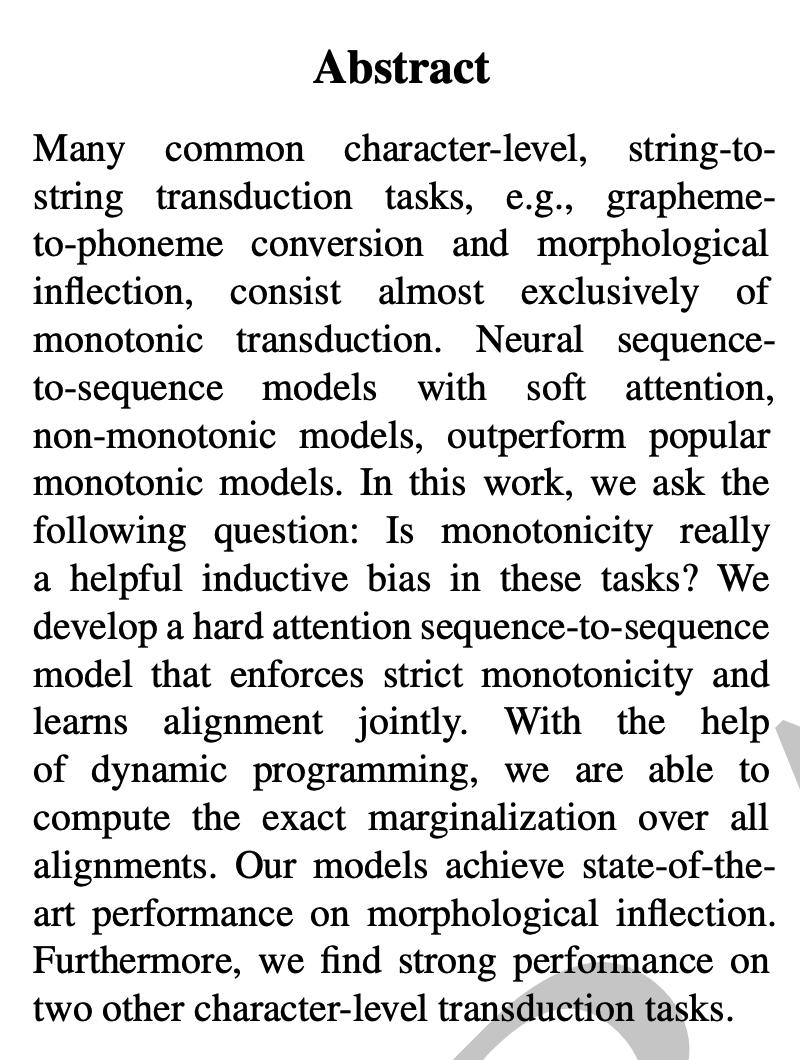
Character-level transduction tasks are mostly monotonic, yet SOTA of morphological inflection is held by non-monotonic models. By jointly learning to monotonically align and transduce, we outperform non-monotonic model and achieve SOTA on morphological inflection
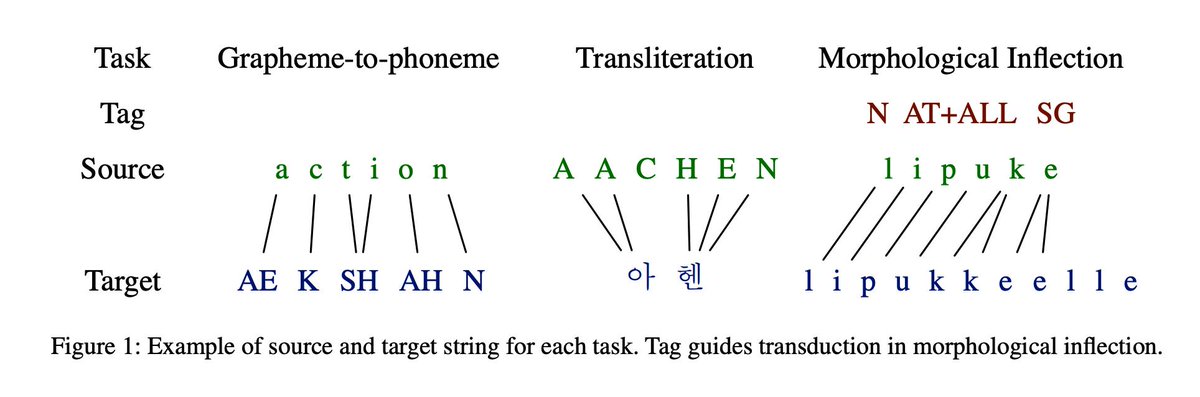
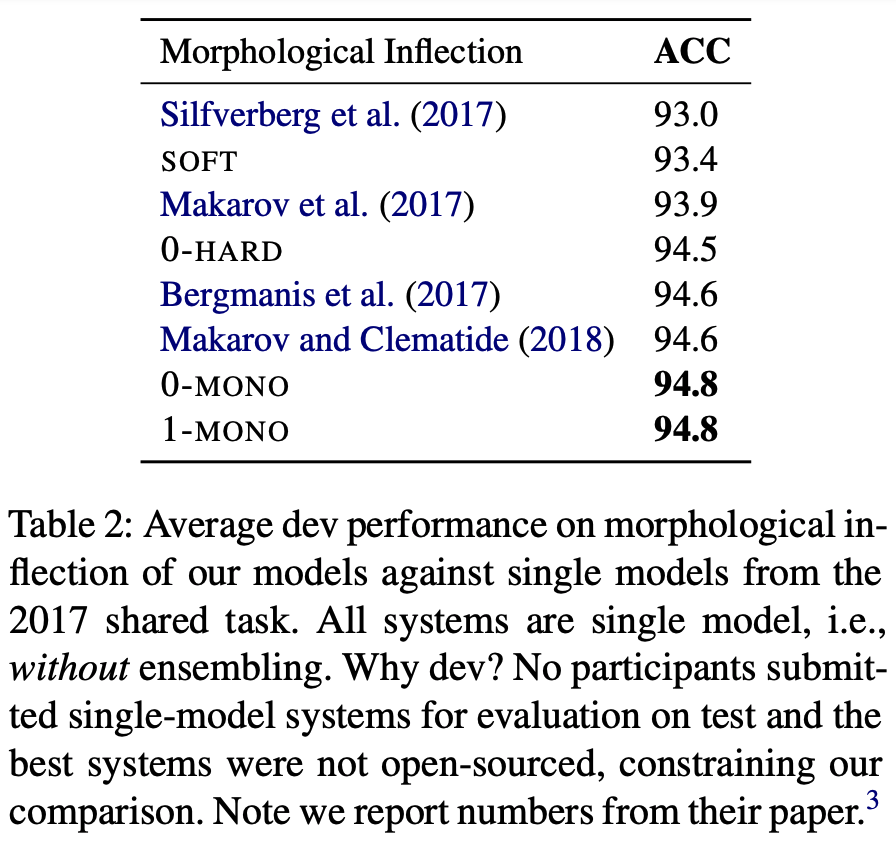
We enforce monotonicity with dynamic programming by turning a 0th order neural HMM into the equivalent 1st-order HMM and introduce structure zeros. It builds on top of our 2018 EMNLP paper, which also includes @pjshap and available in arxiv.org/abs/1808.10024
Check out our paper on the surprising effectiveness of mBERT arxiv.org/abs/1904.09077 We consider zero-shot cross-lingual transfer (NLI, Doc classification, NER, POS tag, dep. parsing). mBERT outperforms embeddings based method on 4 tasks w/o cross-lingual signal. Work w/ @mdredze
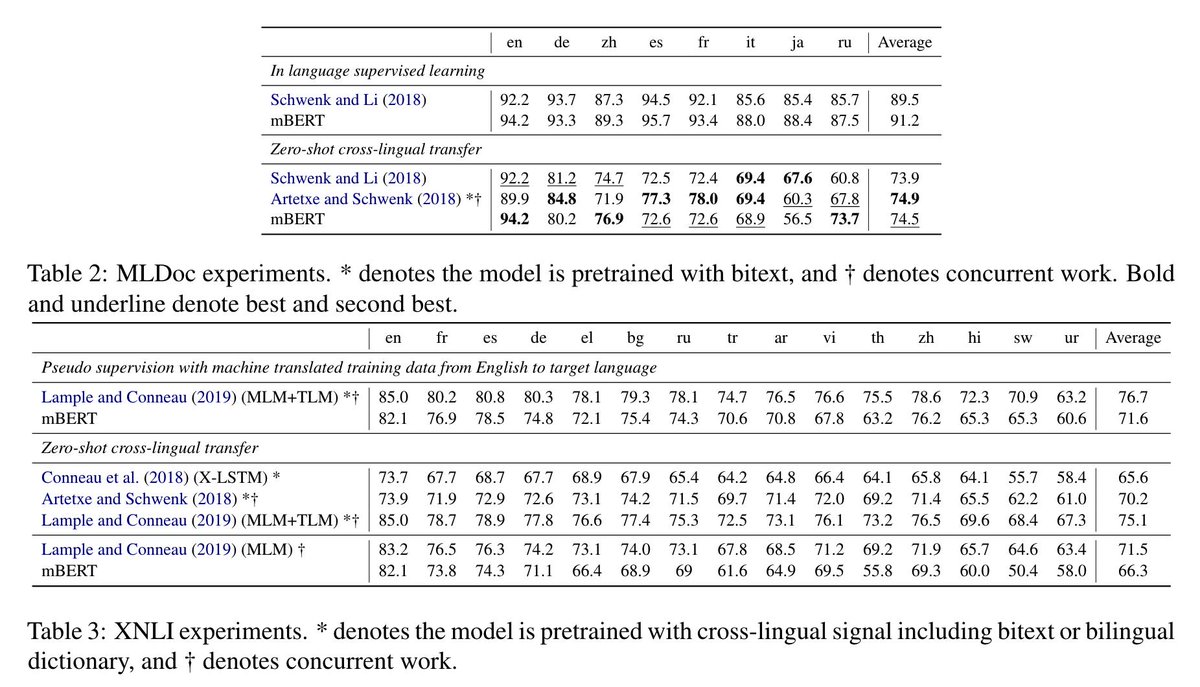
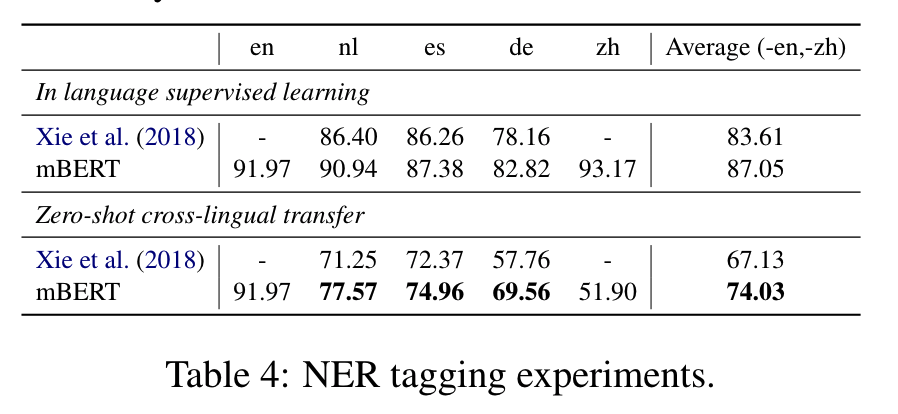
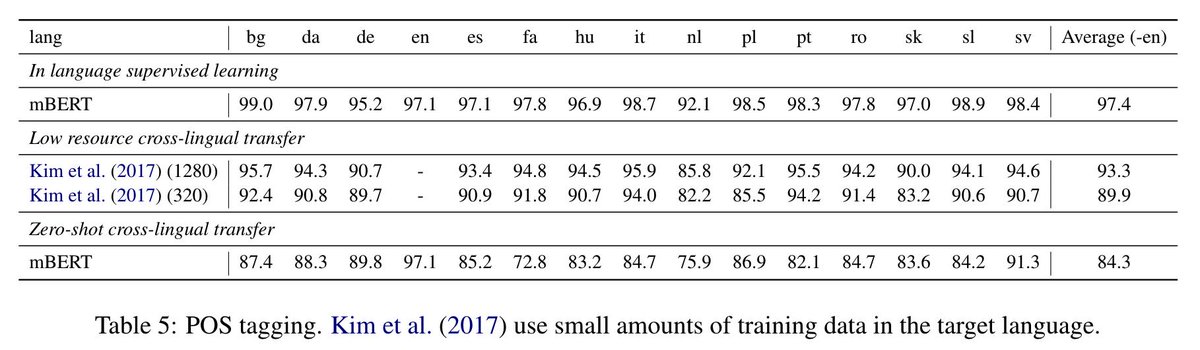
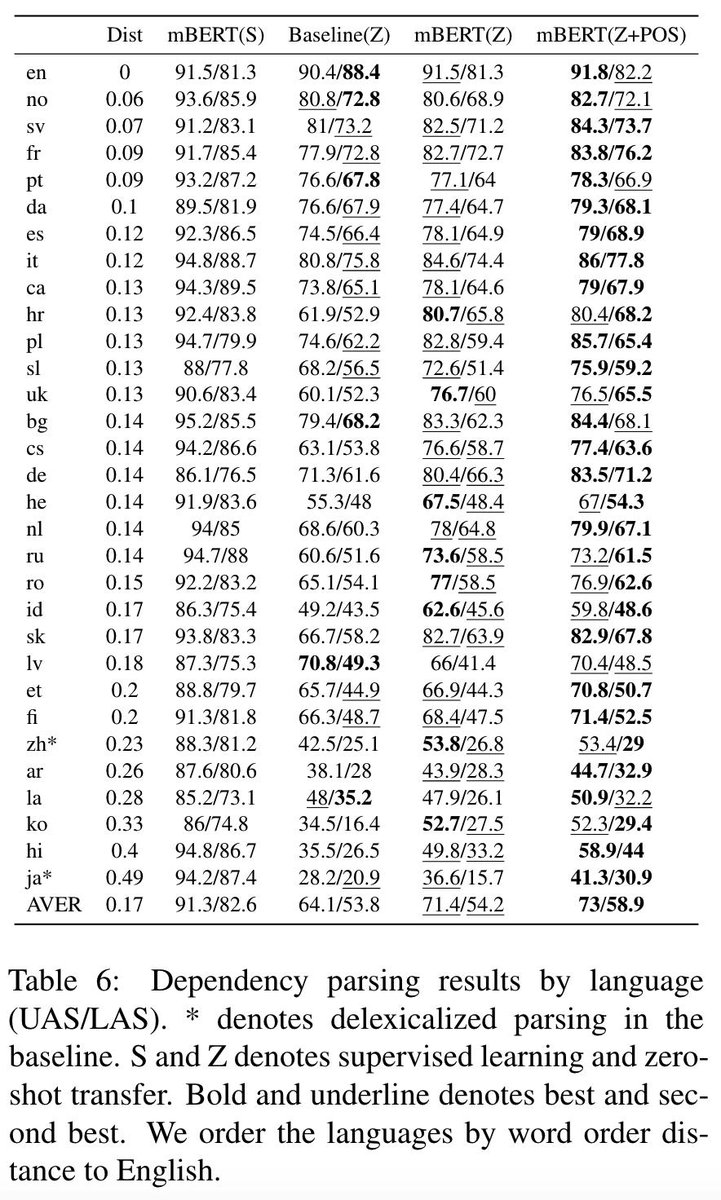
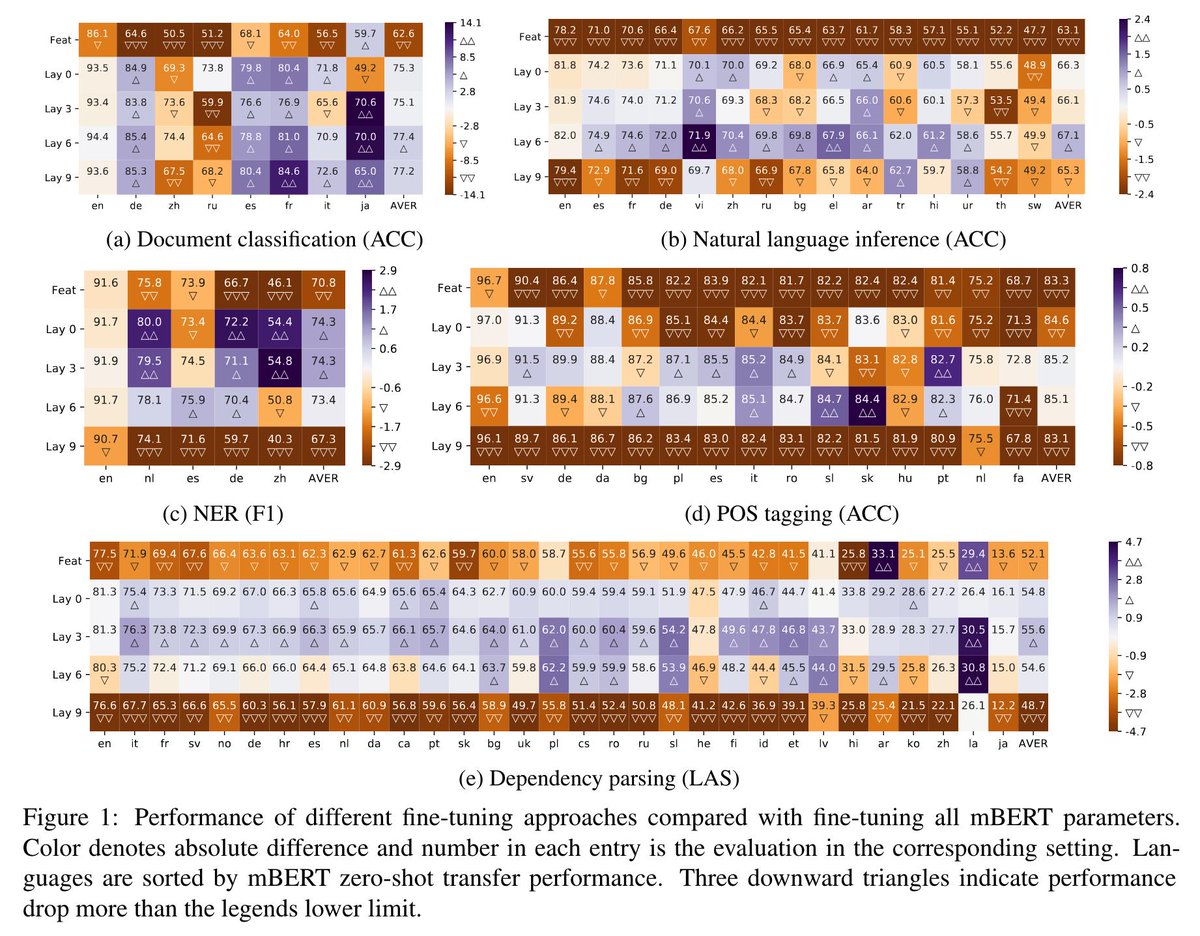
Simply by freezing the bottom X layers of mBERT, we further outperform the fine-tune all baseline. Although X is task dependent
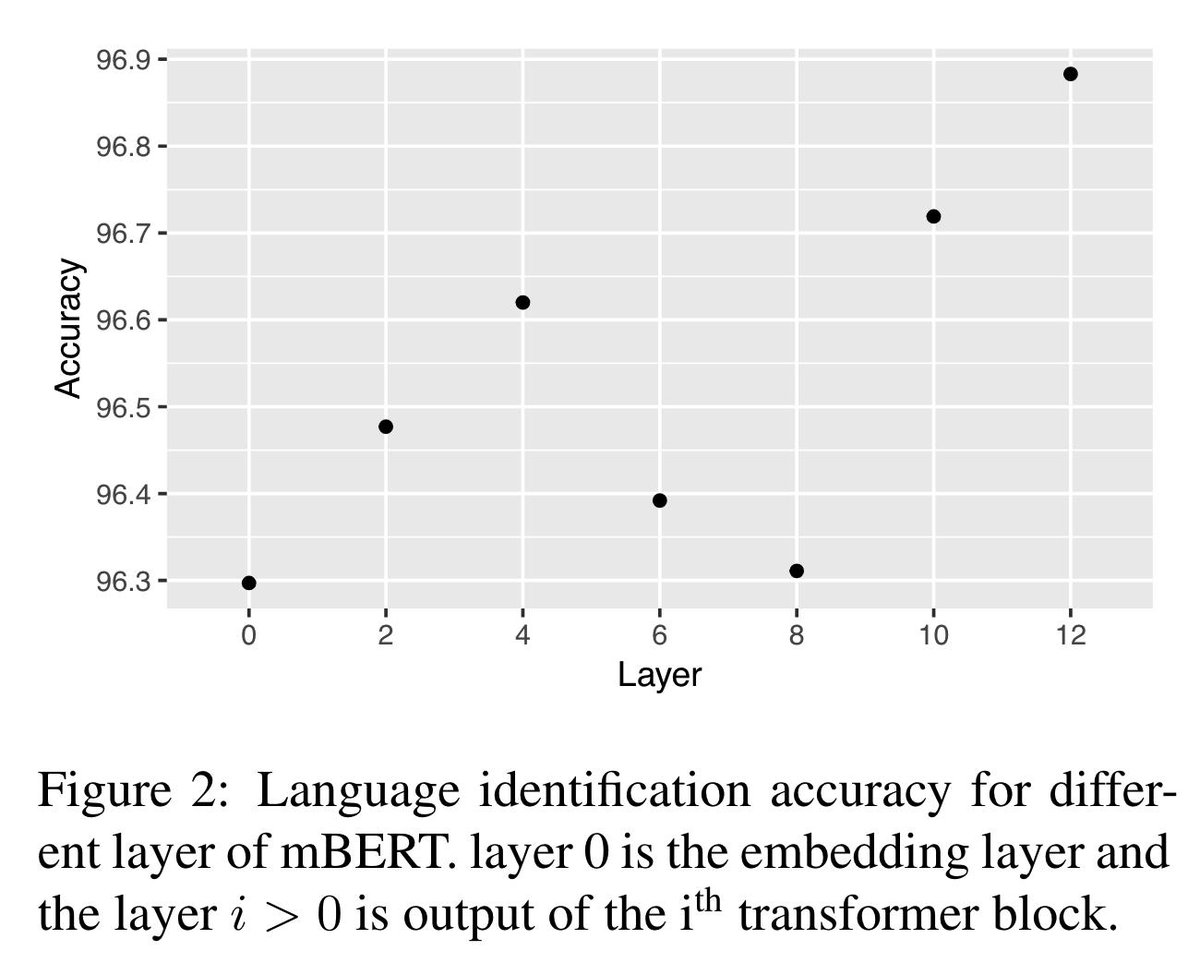
Surprisingly, mBERT still maintains language specific info in each layer despite the strong zero-shot cross-lingual transfer performance. With a simple mean-pooling softmax classifier and *fix* mBERT, it gets over 96% accuracy on 99-way language identification in every layer
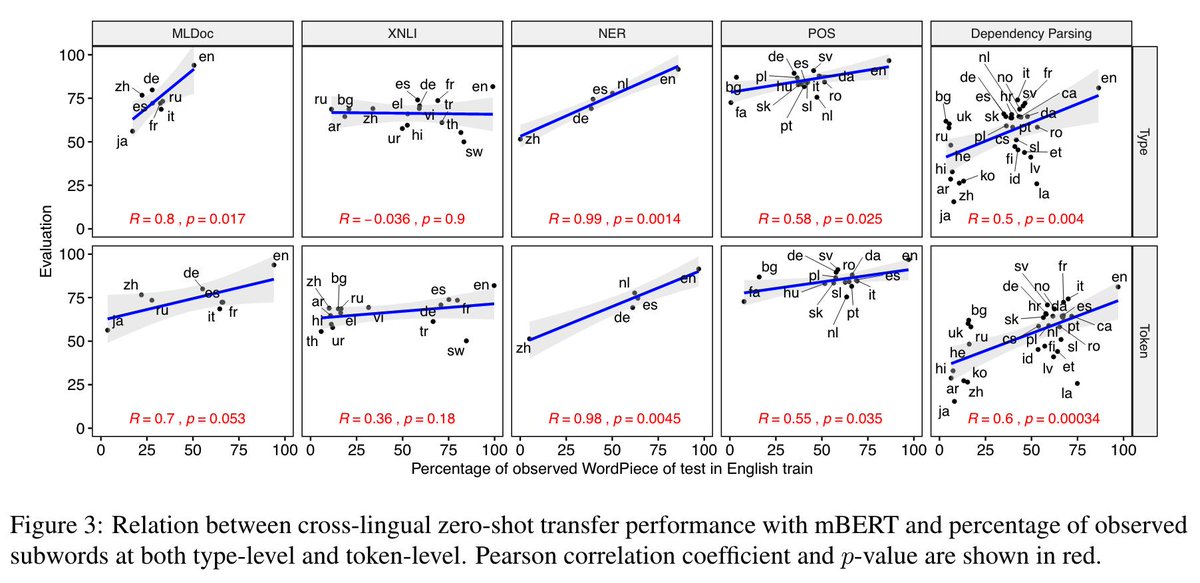
There are concerns on how mBERT share subwords (like DNA) across languages. We show a strong positive correlation between zero-shot cross-lingual performance and type/token level subword overlap